Jacob Willson
  • Home
  • About
  • Contact

Jacob Willson

Projects and experience of Jacob Willson: business intelligence, analytics engineering, and applied AI evaluation.

Jacob Willson

Data analyst and AI research fellow with the Griffiss Institute at the Air Force Research Laboratory. Over ten years in business intelligence and finance analytics at New Balance, Forrester Research, and in consulting; now building data pipelines, GPU inference infrastructure, and LLM evaluations.

M.S. Data Science and Analytics, SUNY Polytechnic Institute, May 2027 · Clinton, New York

Projects Experience

ProjectsAnalytics engineeringDecision scienceApplied AI

Each card links to a repository with the code, data or data generator, results, and stated limitations. Select a figure to enlarge it.

Analytics Engineering and Data Platforms
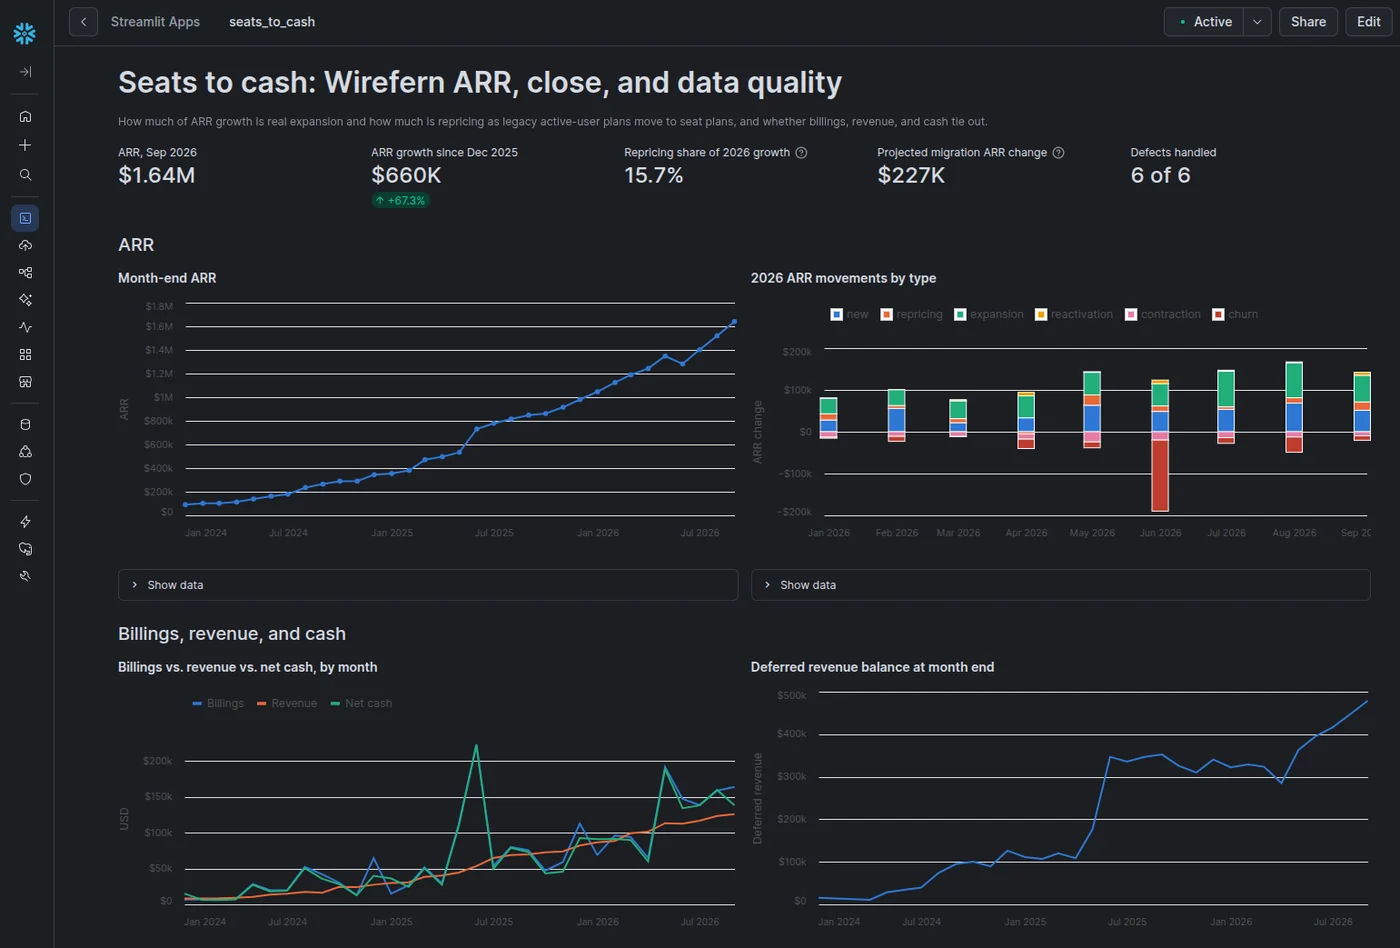
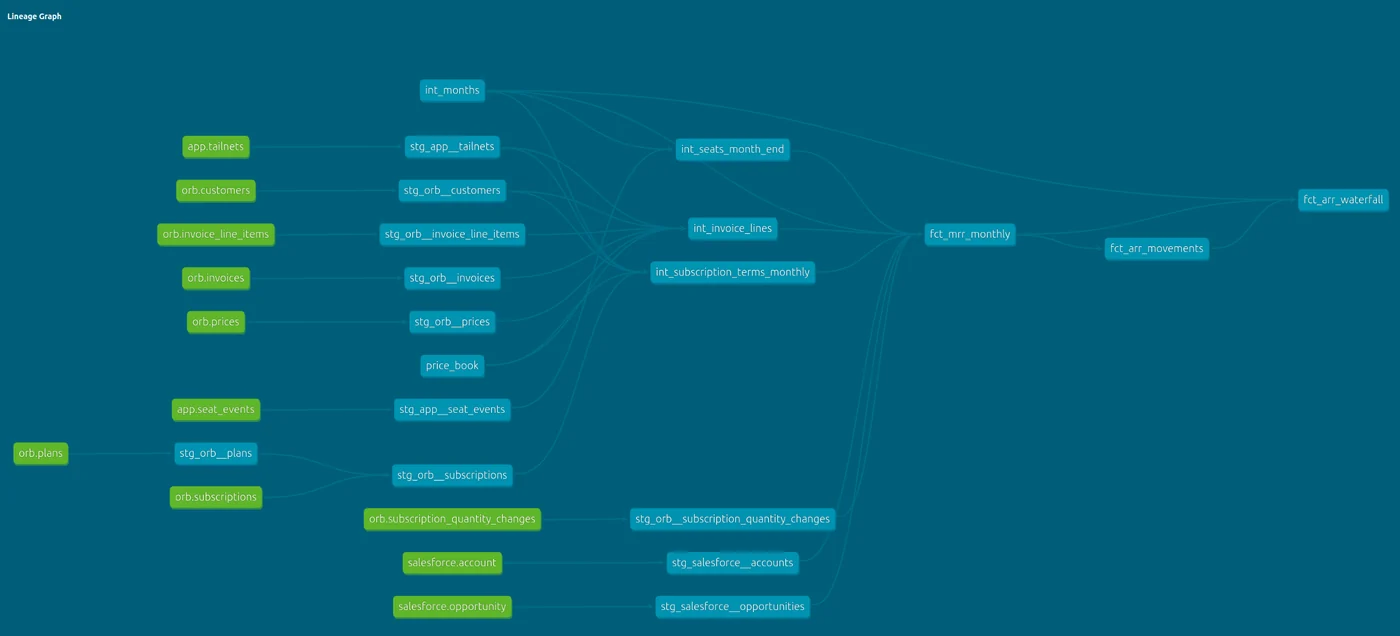
Seats-to-Cash Streamlit app showing month-end ARR, ARR movements by type, and billings, revenue, and cash by month 3 figures

Analytics engineering · Financial data · Reconciliation

Seats-to-Cash

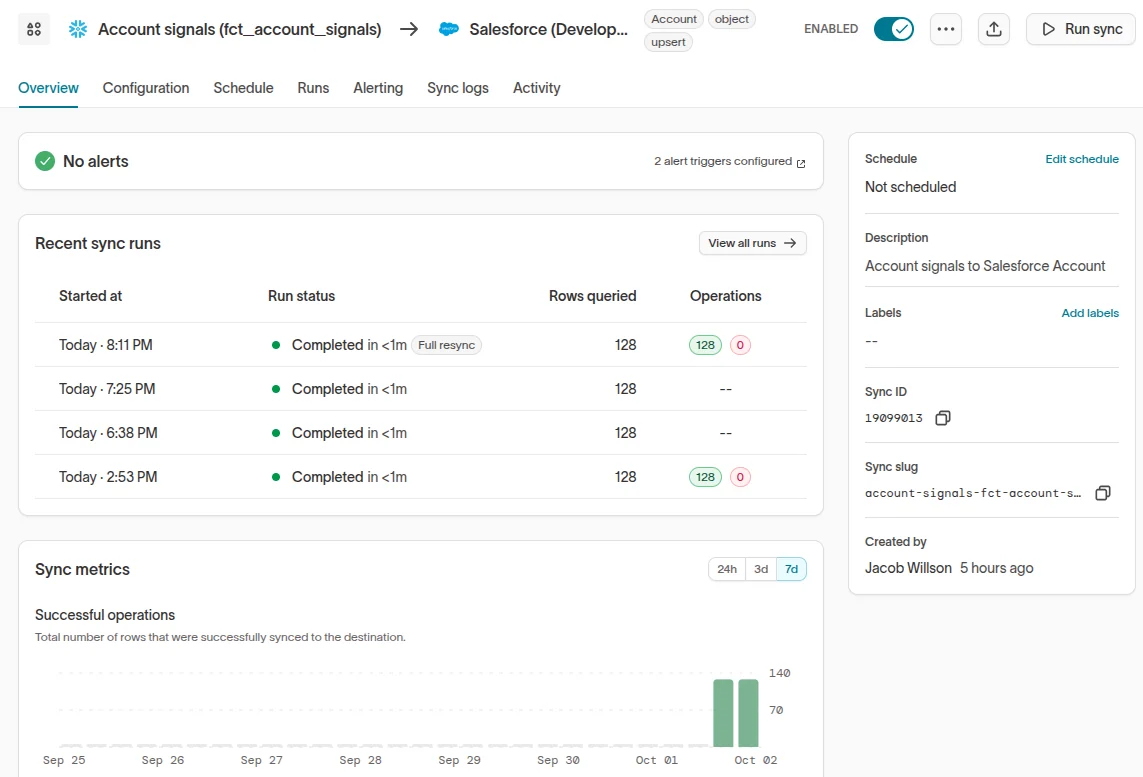
A dbt and Snowflake finance stack on synthetic Orb, Stripe, and Salesforce data that reconciles billings, revenue, deferred revenue, and cash, and syncs account signals to Salesforce via Hightouch.

Key finding15.7% of 2026 ARR growth was repricing rather than expansion, with every MRR and revenue figure matching the answer key to the cent.

dbt · Snowflake · DuckDB · Hightouch · Streamlit · LookML
View repository →

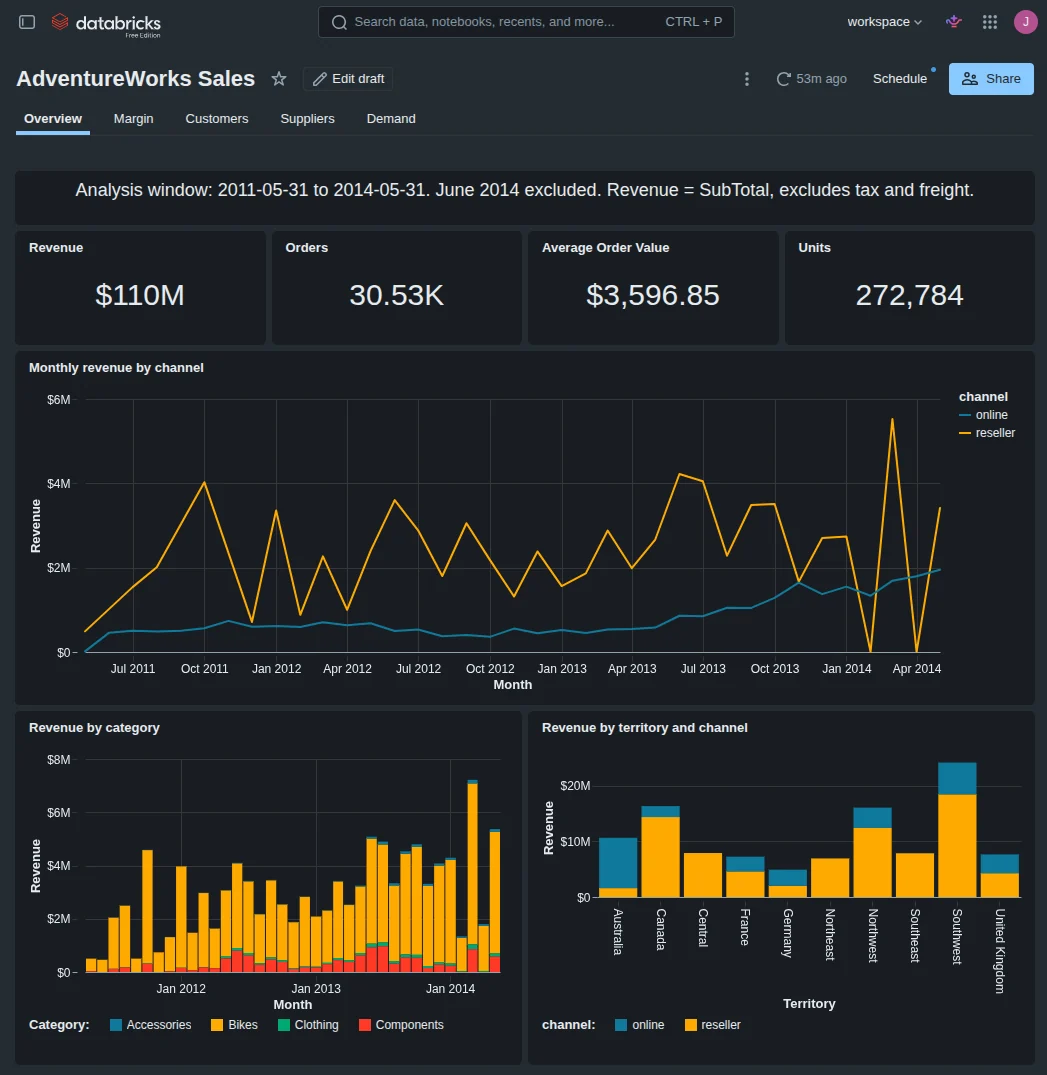
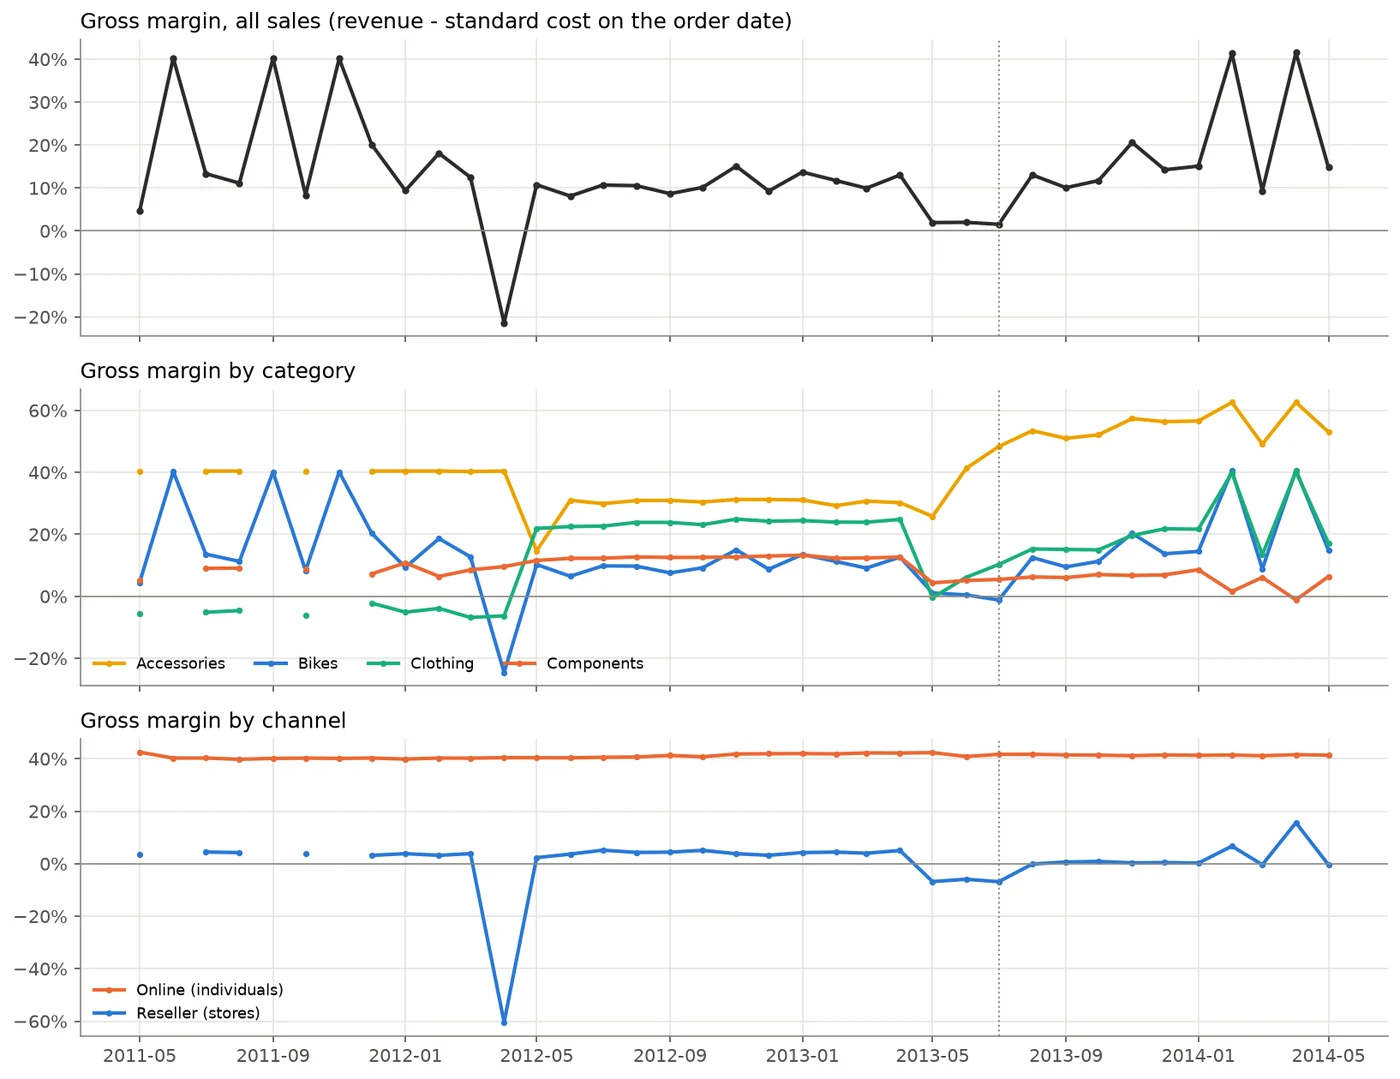
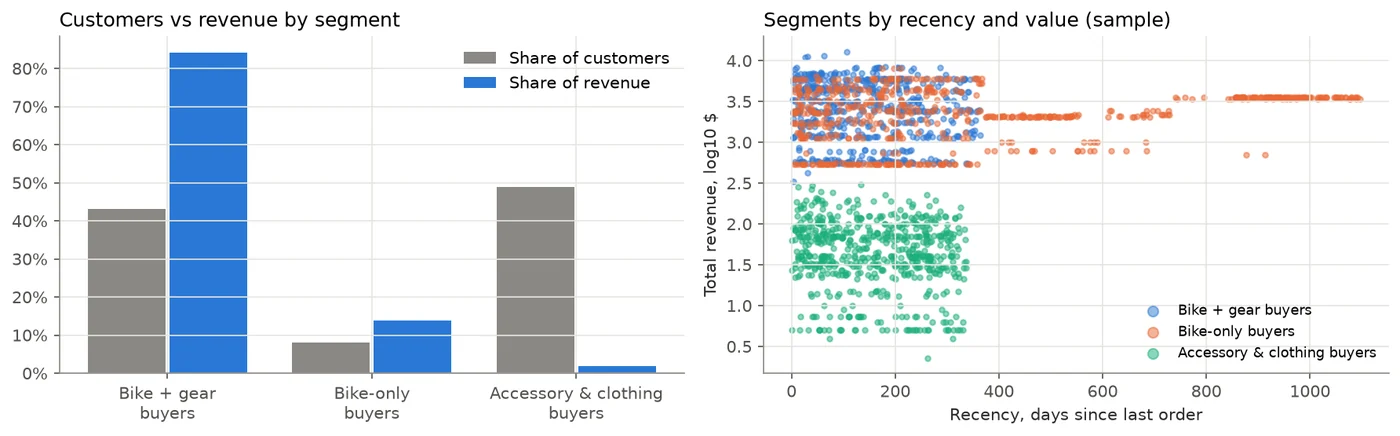
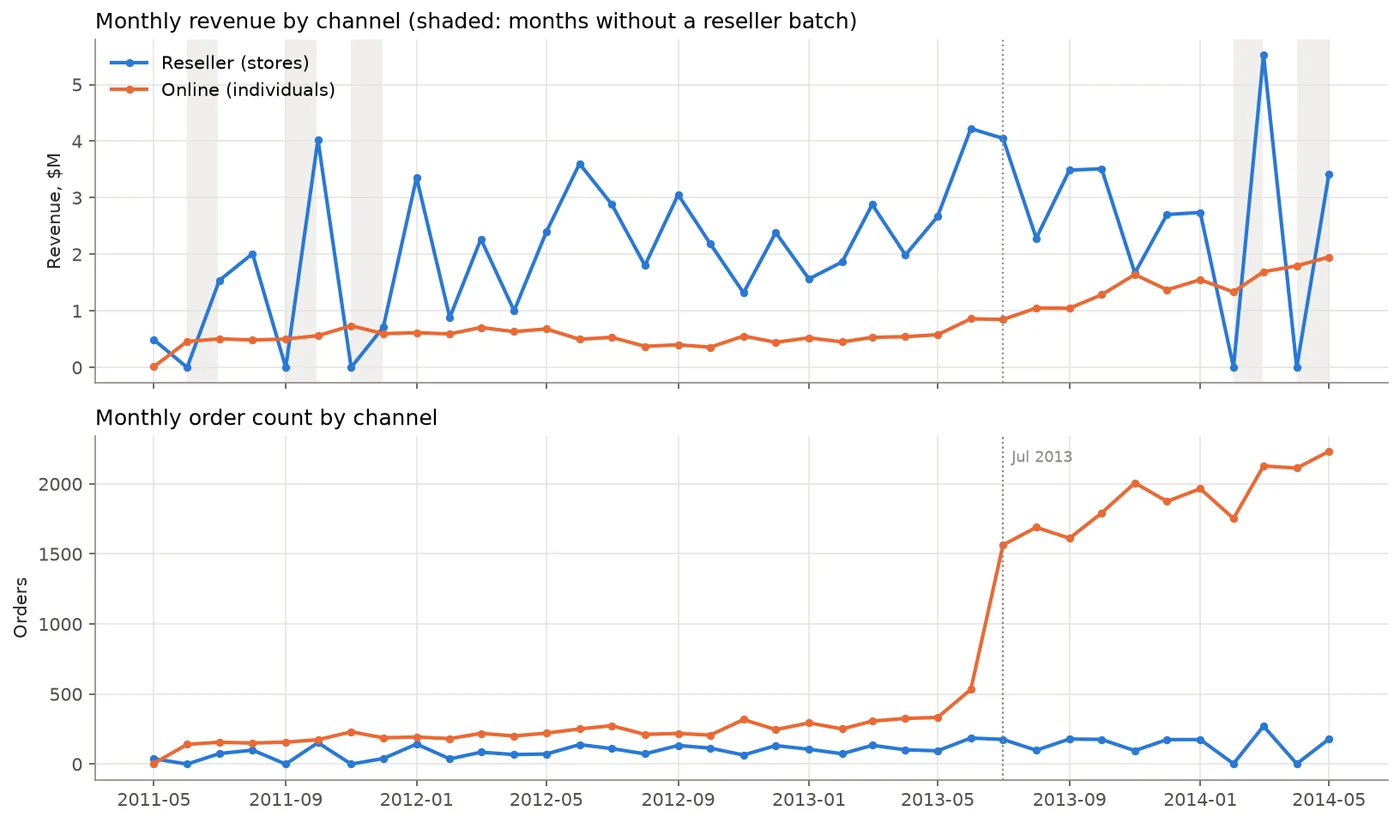
Line charts of monthly revenue and order count by channel, with online orders jumping from about 330 to over 1,500 a month after July 2013 4 figures

Data engineering · Lakehouse · Analytics

AdventureWorks Lakehouse

A Databricks medallion lakehouse that turns a broken 72-file export into a dbt star schema with 148 tests, MLflow-tracked analyses, and a five-page AI/BI dashboard, deployed as one Asset Bundle.

Key findingResellers bring about three quarters of revenue at a 0.6% gross margin, while online holds a steady 40%. Forecasting did not beat a naive baseline (49.0% vs 49.4% WAPE), and the write-up reports that rather than hiding it.

Databricks · PySpark · Lakeflow · dbt · MLflow · AI/BI dashboards
View repository →

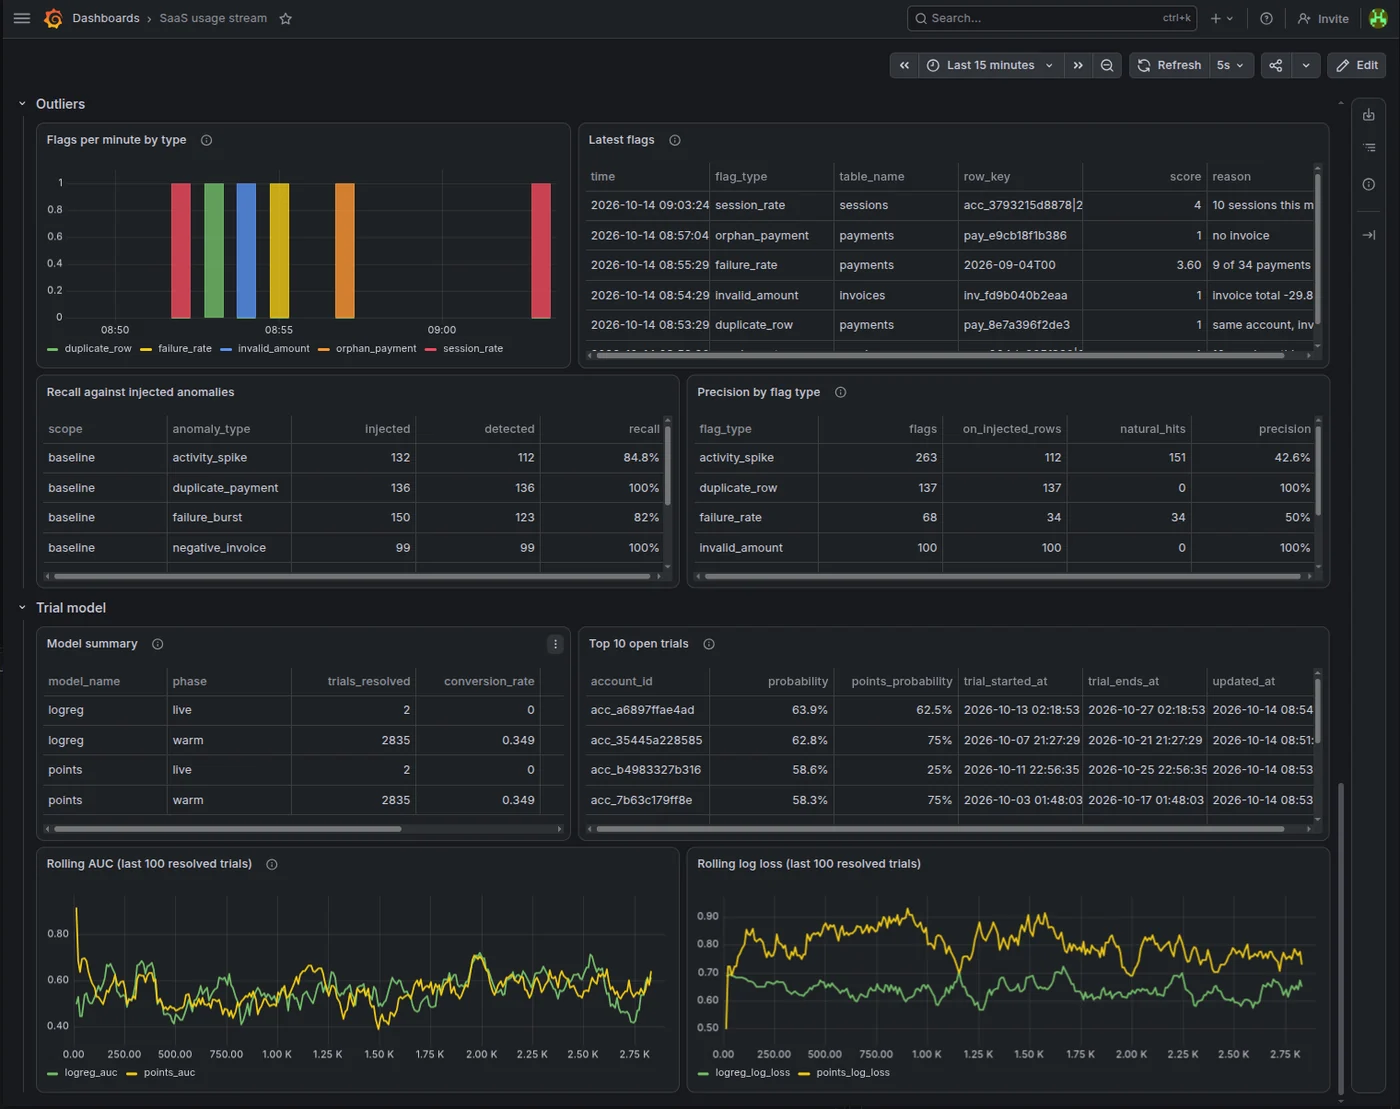
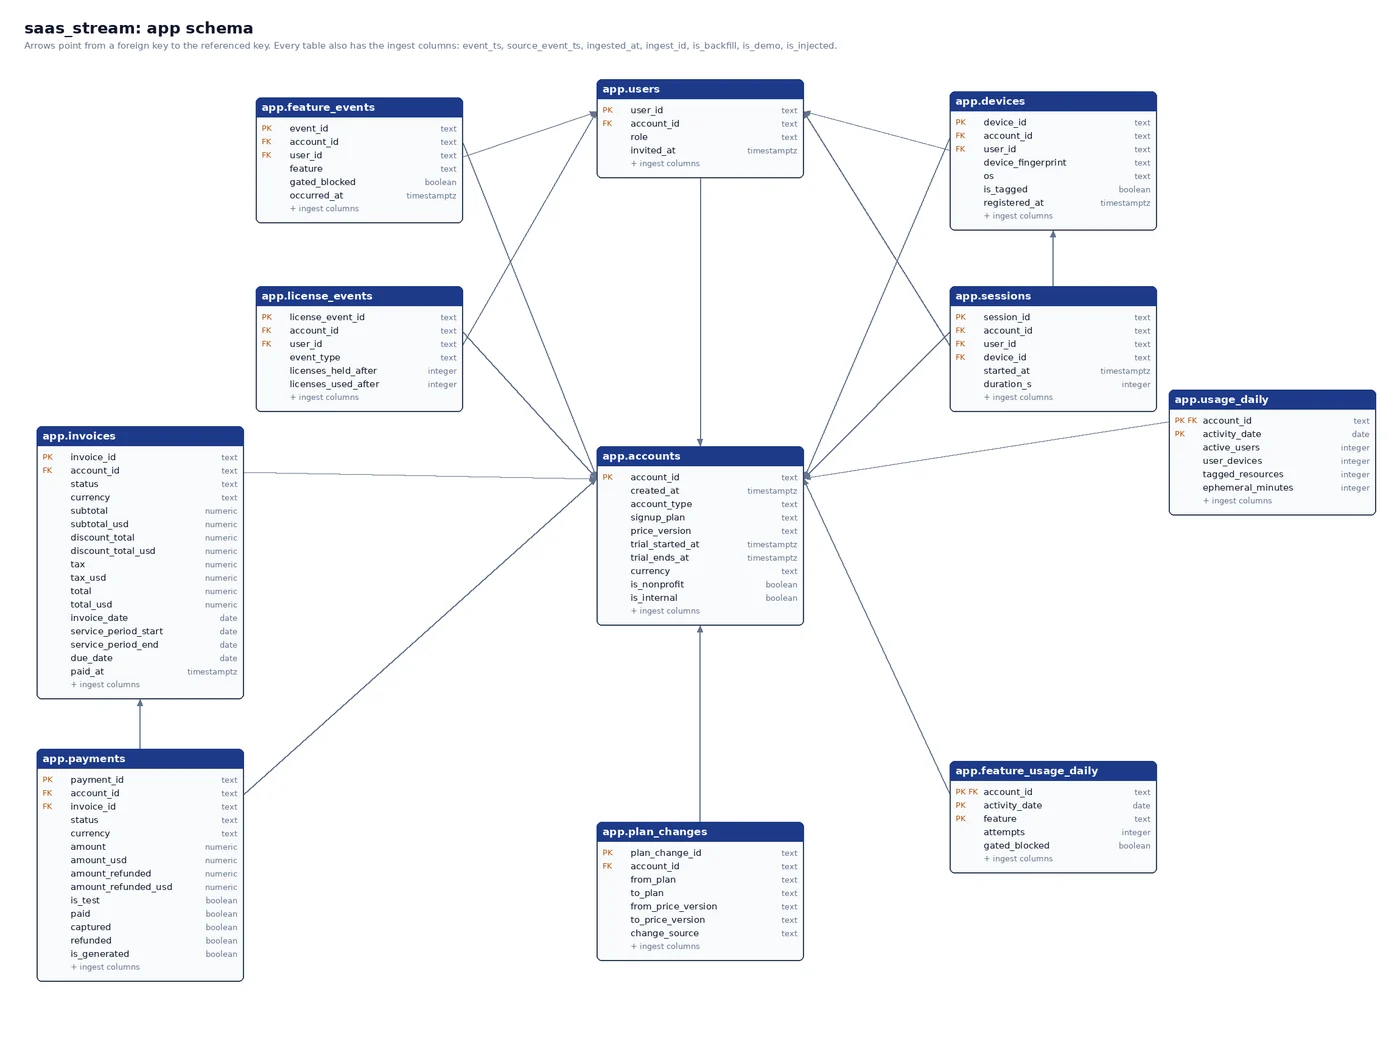
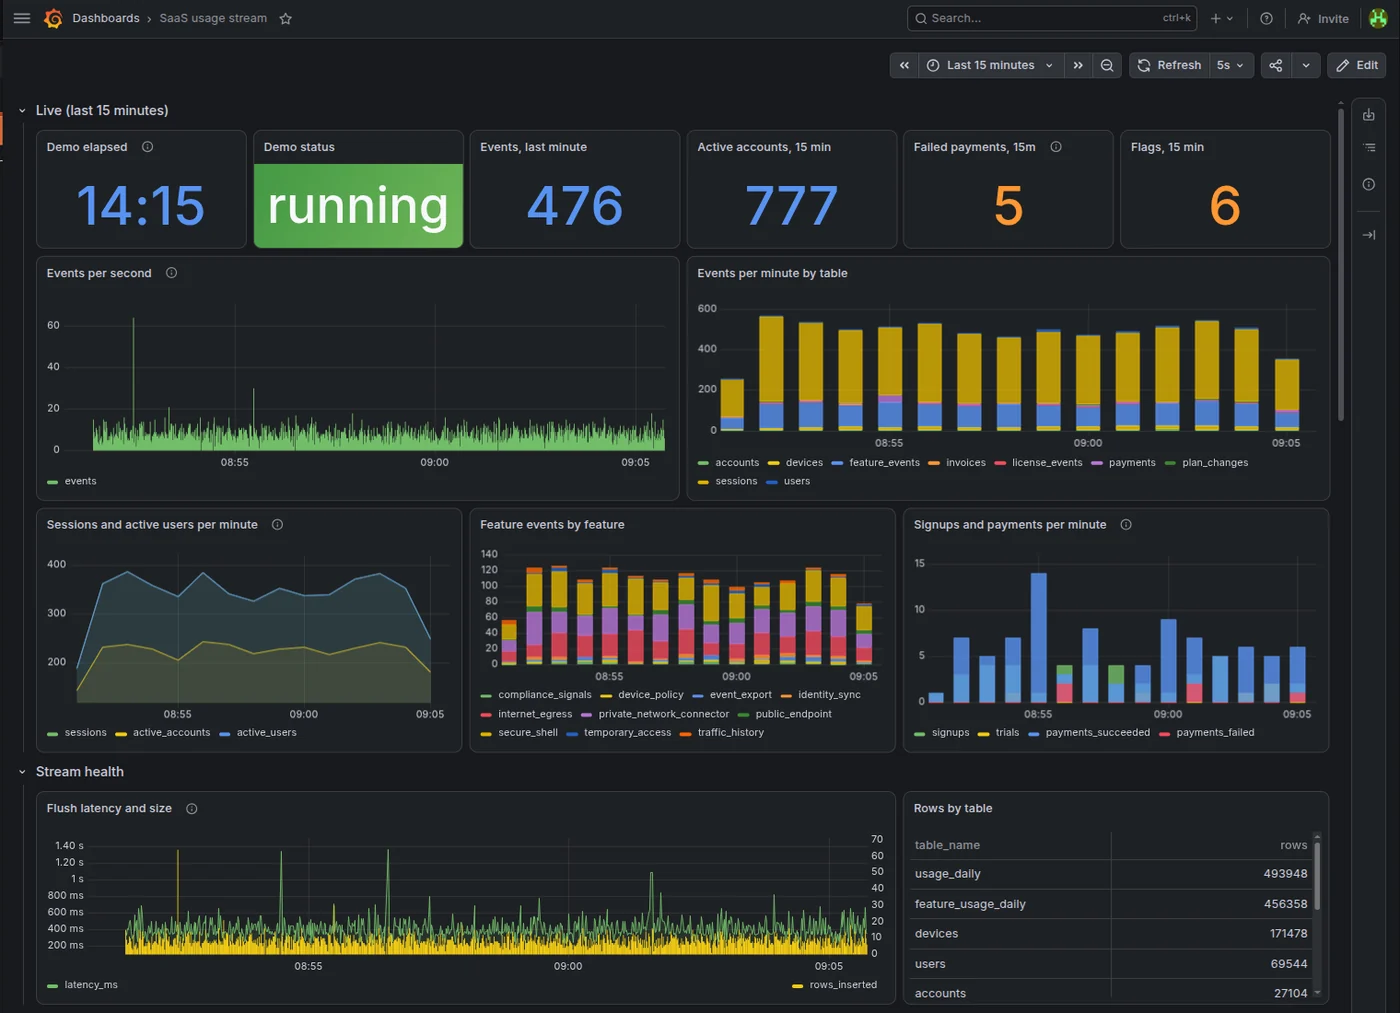
Azure Managed Grafana dashboard streaming live SaaS events, showing 476 events in the last minute, 777 active accounts, and outlier flags 3 figures

Streaming analytics · Azure · Anomaly detection

SaaS Usage Streaming on Azure

A real-time pipeline streaming about 500 events per minute into Azure PostgreSQL, with live outlier detection, an online trial-conversion model, and a 42-panel Managed Grafana dashboard.

Key findingDuplicate payments and negative invoices were caught at 1.00 recall and precision, about 2.5 seconds after landing. A first-pass 0.71 AUC for trial conversion turned out to be label leakage; the corrected holdout AUC is 0.54.

Python · PostgreSQL · Azure · Grafana · SQL

View repository →

Experimentation and Decision Science

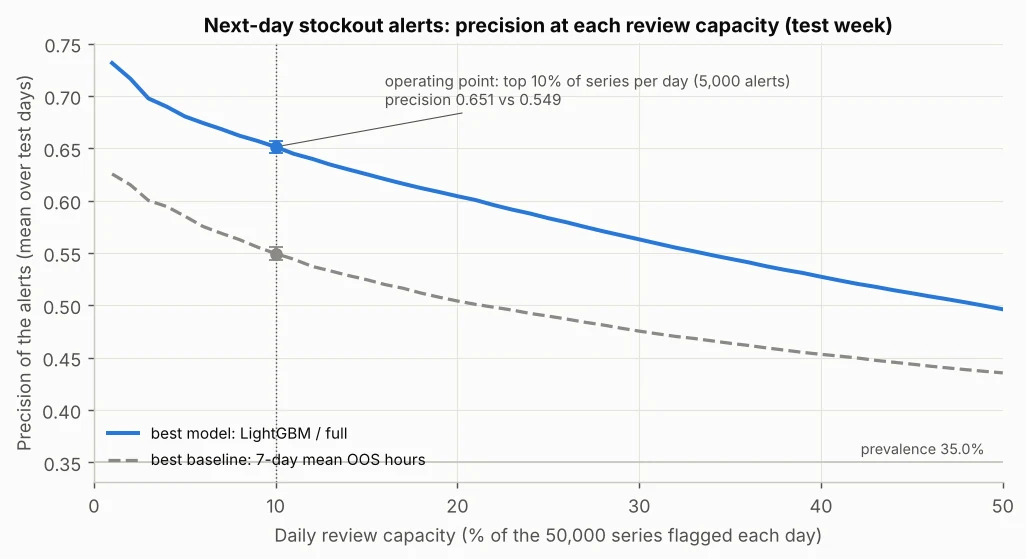
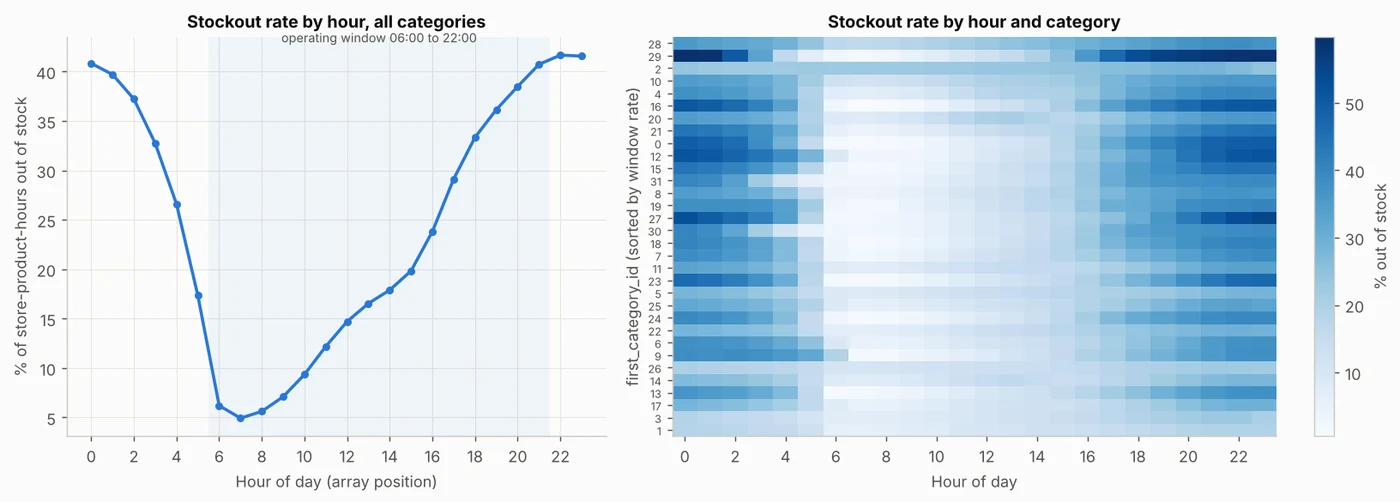
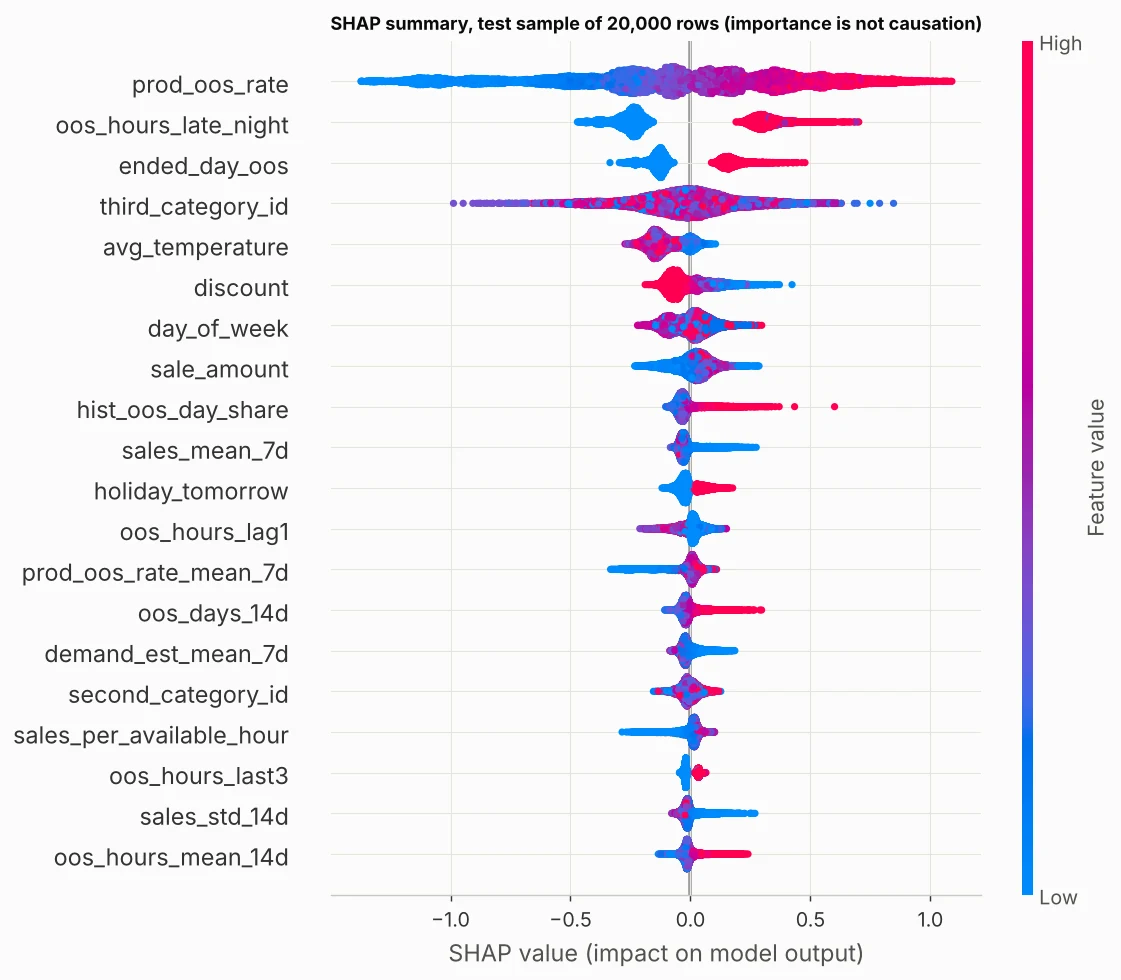
Line chart of precision by daily review capacity: the model reaches 0.651 at the top 10% of series against 0.549 for the best baseline 3 figures

Predictive modeling · Retail · Model evaluation

Next-Day Stockout Alerts

A model that ranks 50,000 perishable store-product series each evening by their risk of running out tomorrow, built on a SQL feature pipeline and evaluated with a rolling backtest and store-level bootstrap intervals.

Key findingAt 5,000 alerts a day, 65.1% were real stockouts against 54.9% for the best simple baseline, driven mostly by the same product running out in other stores. It catches about 19% of next-day stockouts at that capacity, so it works as a ranking aid.

Python · SQL · DuckDB · LightGBM · SHAP · pytest
View repository →

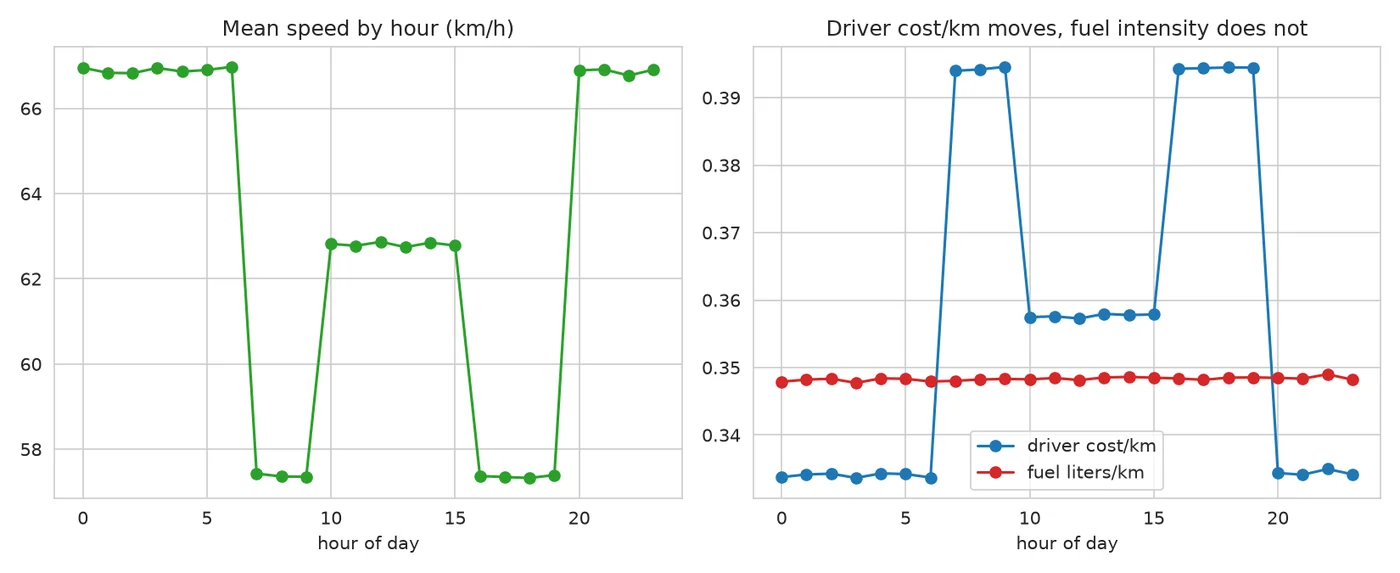
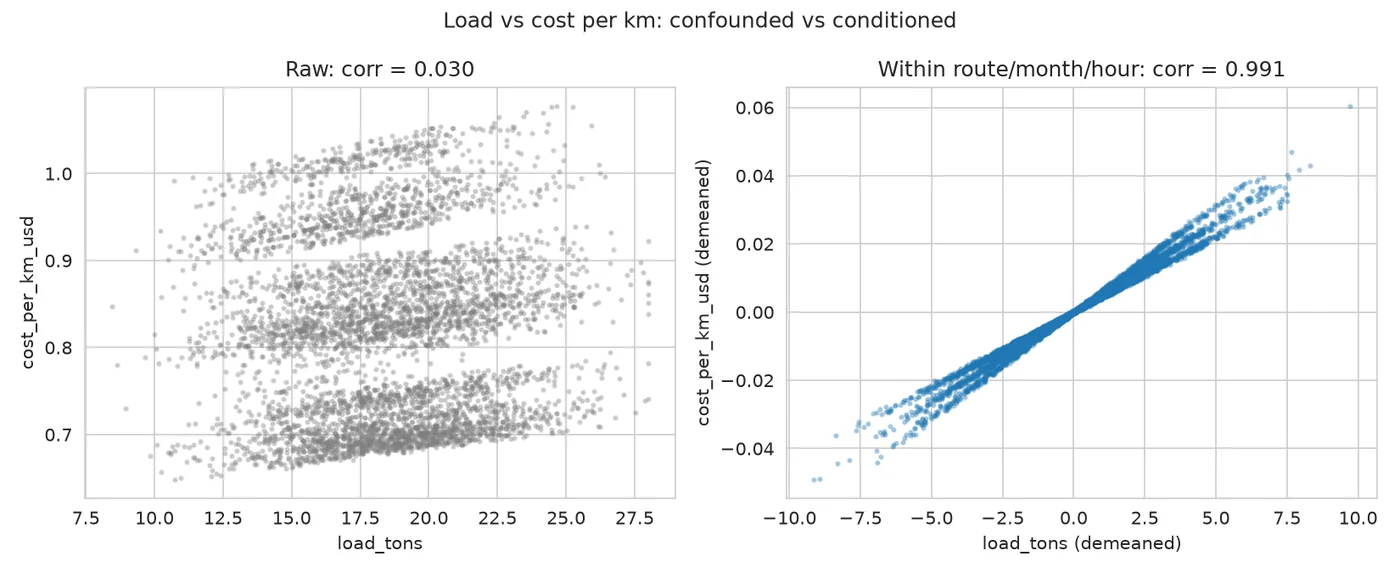
Two scatter plots: raw load vs cost per km with correlation 0.030, and the same relationship within route, month, and hour with correlation 0.991 3 figures

Decision science · Sampling · Segmentation

Freight Cost & Sampling Analysis

A 500,000-trip synthetic freight network used to test sampling designs, cost drivers, and confounding controls against a fully known population.

Key findingLike-for-like controls increased the observed load–cost correlation from 0.030 to 0.991.

Python · pandas · Statistical analysis · Data visualization
View repository →

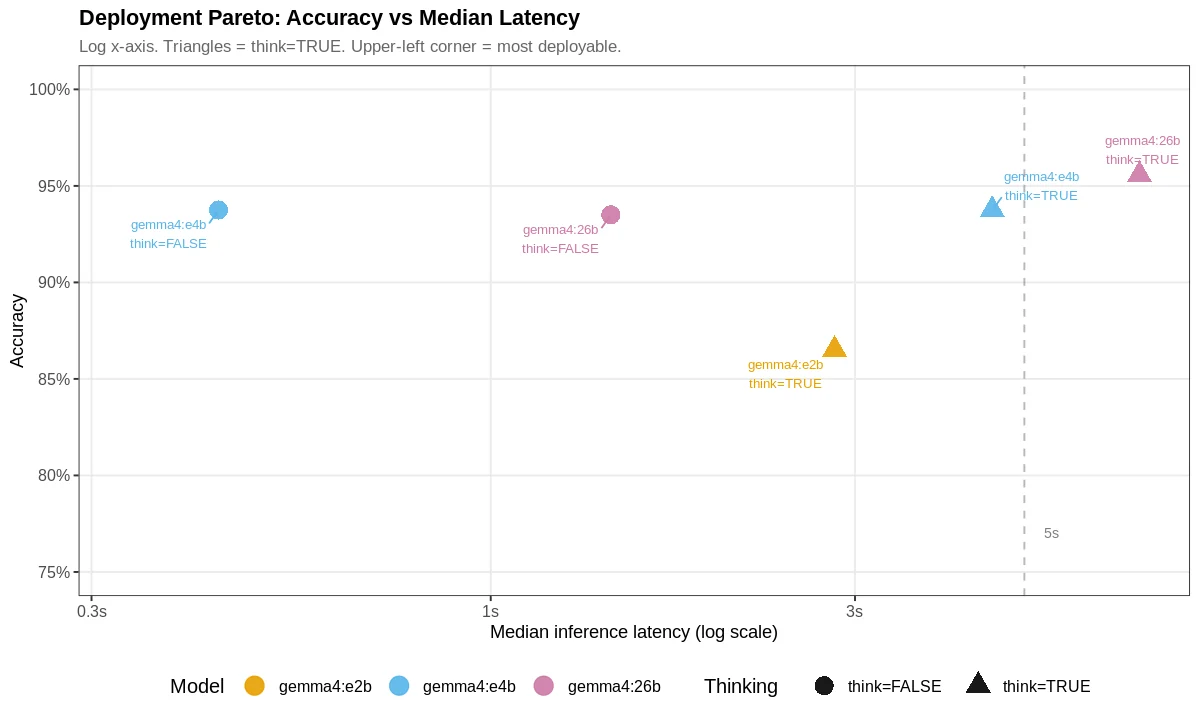
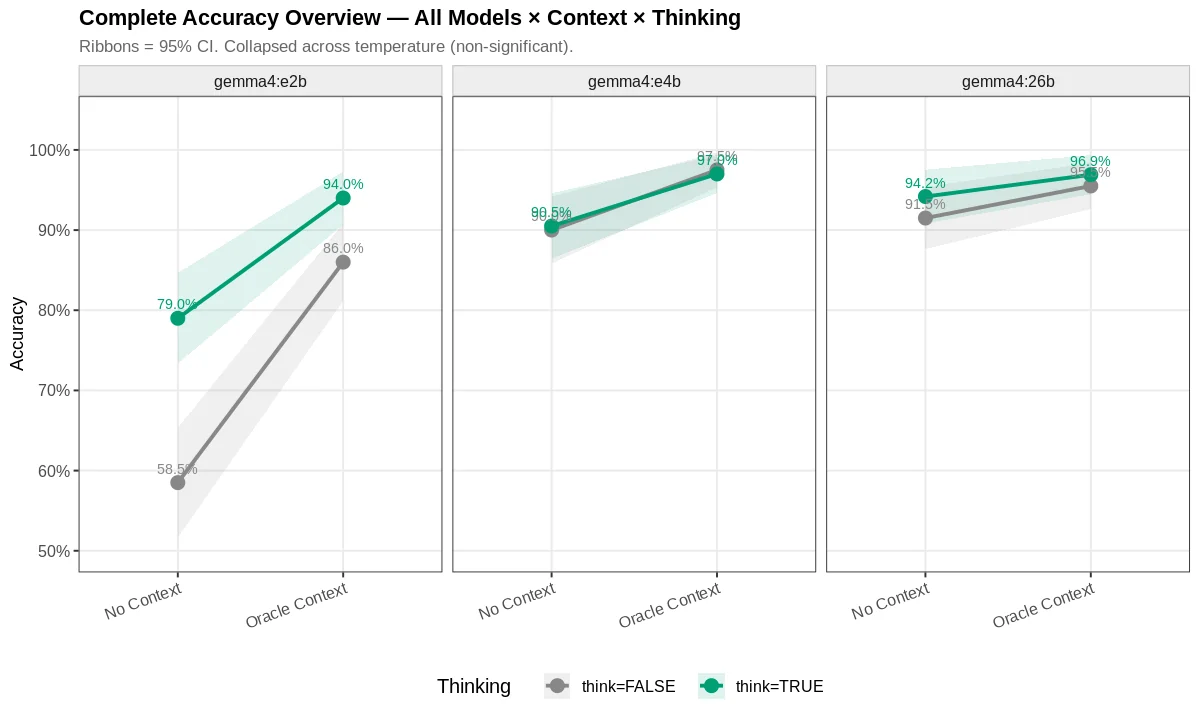
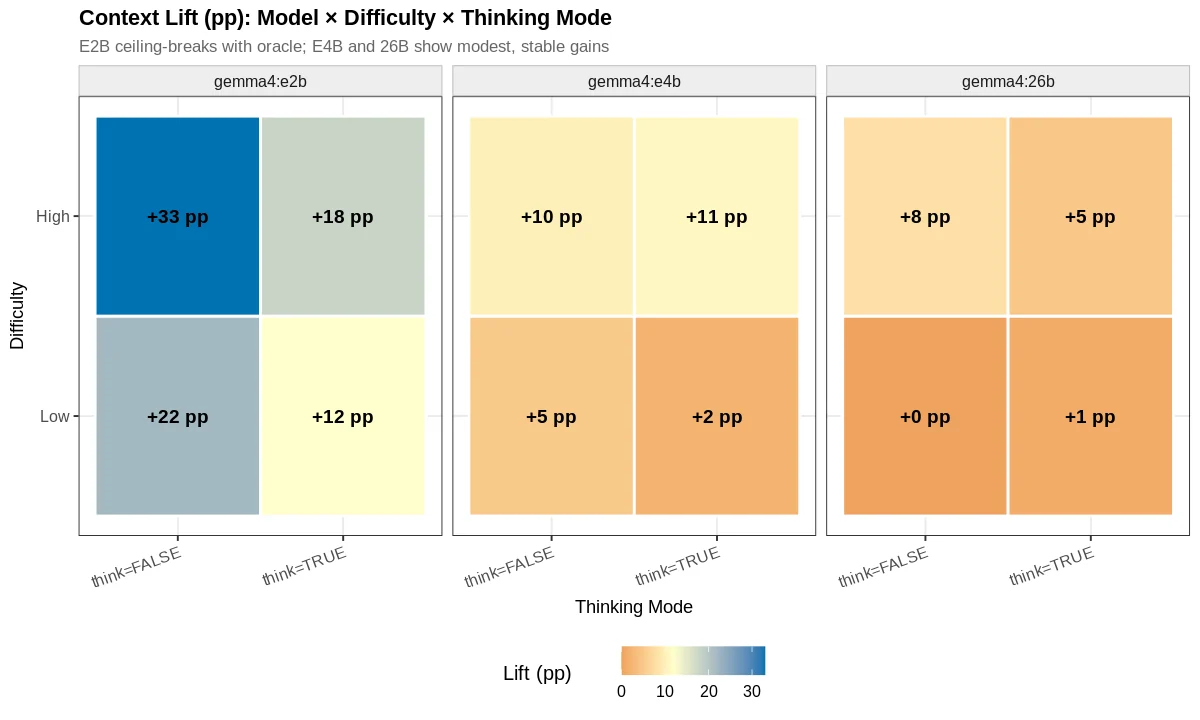
Heatmap of accuracy lift from oracle context by model, difficulty, and thinking mode, peaking at 33 points for the smallest model on hard questions 3 figures

Experimental design · LLM evaluation · Deployment

Gemma 4 Security-Advisory Evaluation

A factorial experiment across 3,900 local inference runs measuring how model size, supplied evidence, thinking mode, and temperature affect accuracy and latency on security-advisory questions.

Key findingOracle context lifted the smallest model by up to 33 points on hard questions. E4B with thinking off reached 93.8% at 0.44 s median latency; 26B led at 95.6% but took 7.08 s, about 16 times longer.

Python · R · Ollama · Factorial design · ANOVA
View repository →

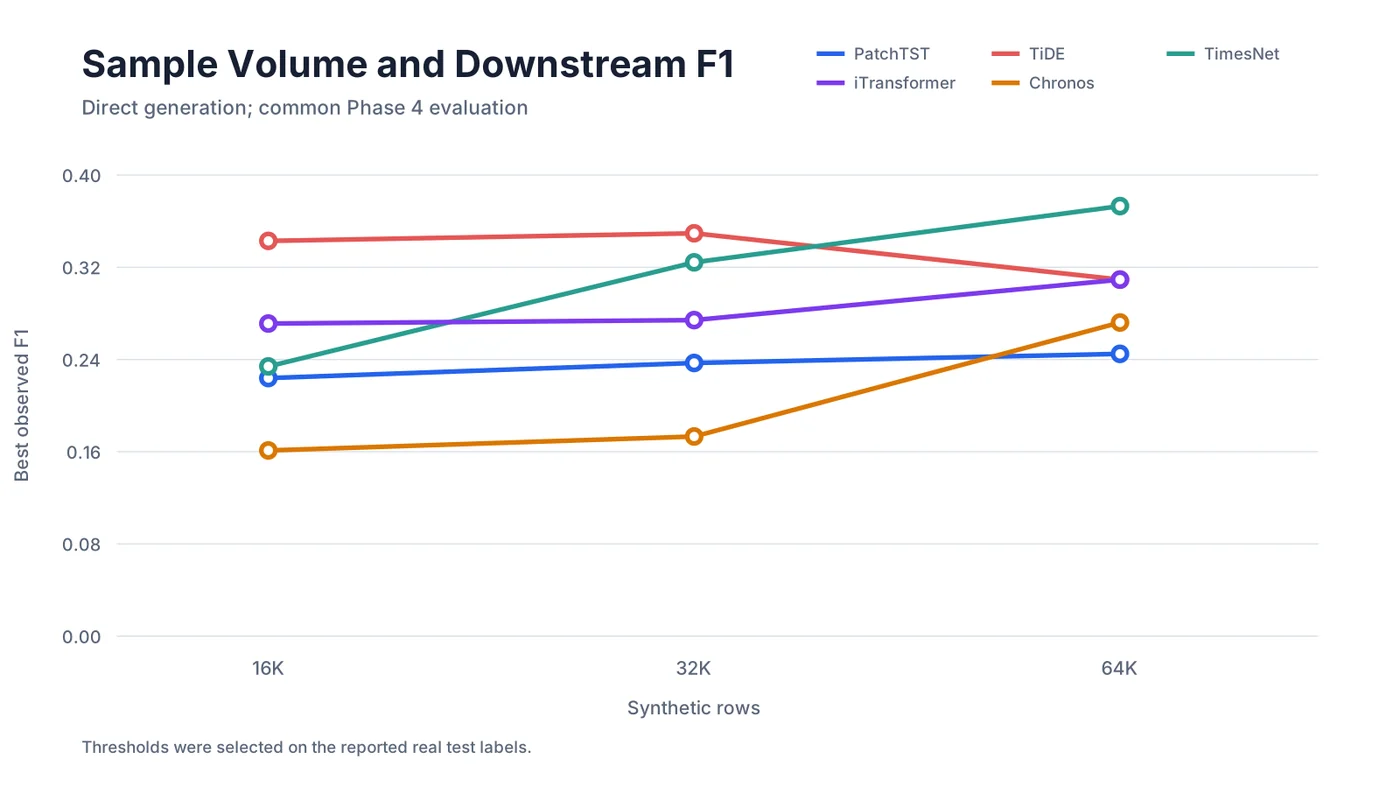
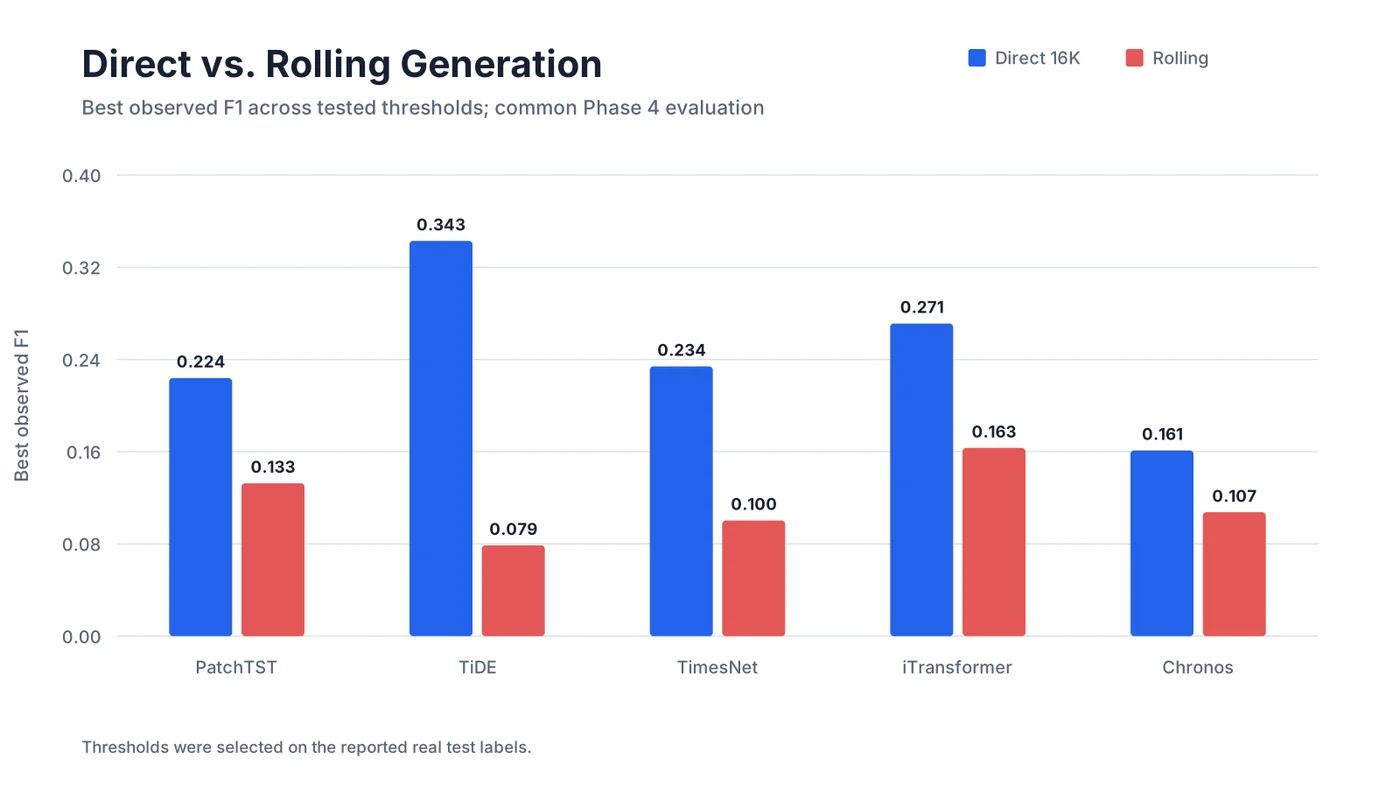
Bar chart comparing direct and rolling synthetic generation across five time-series architectures; rolling scores lower for every architecture 2 figures

Synthetic data · Time series · Predictive evaluation

Synthetic UAV Telemetry Evaluation

Seven synthetic time-series generators compared on two UAV datasets for statistical fidelity and train-synthetic/test-real utility.

Key findingEvery rolling-generation variant scored below its direct counterpart, cutting downstream F1 by 33% to 77% across five architectures. Matching class balance did not produce matching predictive structure.

Python · PyTorch · GCP A100 · Time-series modeling
View repository →

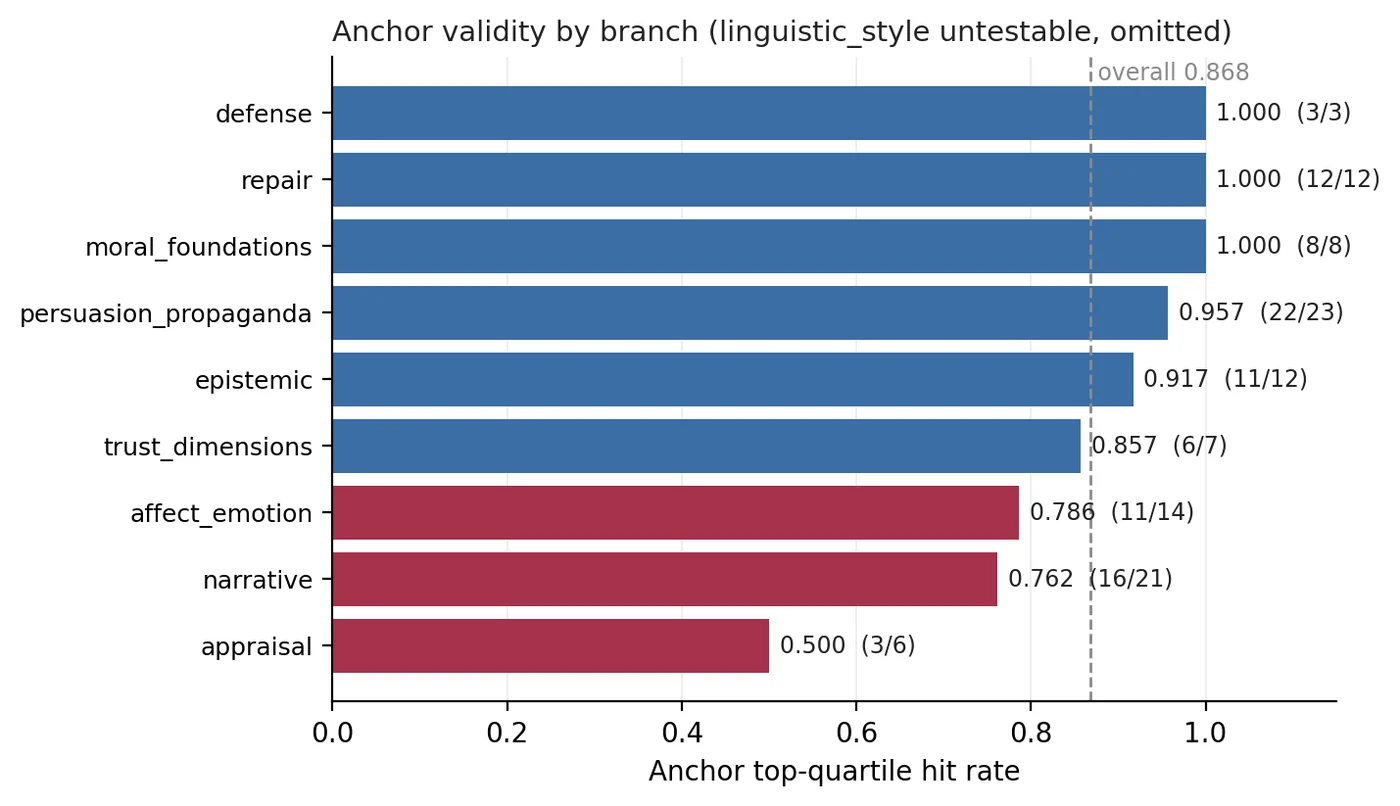
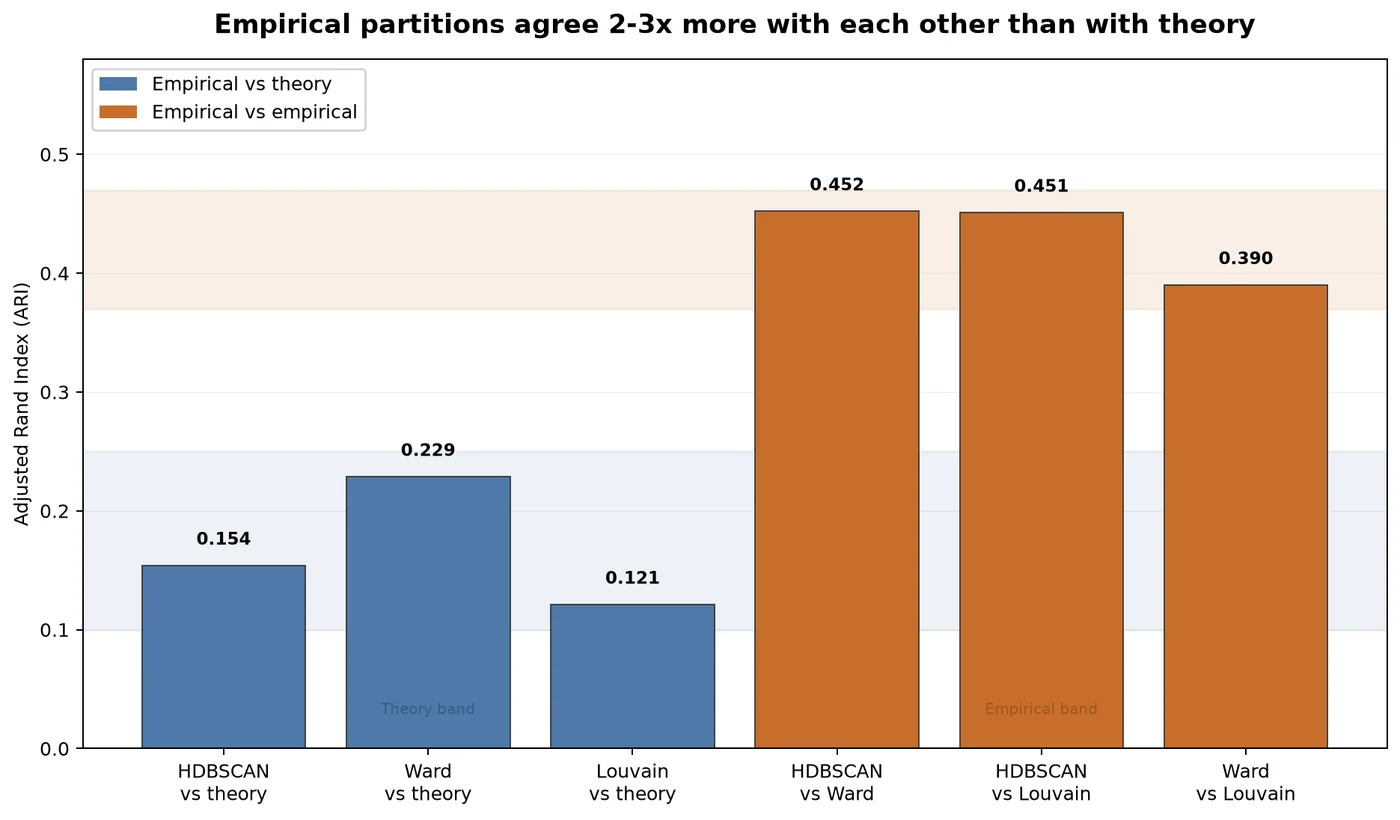
Bar chart of Adjusted Rand Index showing empirical clusterings agree with each other at 0.39 to 0.45 but with theory at only 0.12 to 0.23 2 figures

NLP · Ontology validation · Research methods

SCIO Ontology Validation

Validation of a 121-feature influence-technique ontology using literature scoring, LLM-assisted coding, embeddings, clustering, and structured human review.

Key findingThree clustering methods agreed with each other 2 to 3 times more than with the theoretical branches (ARI 0.39 to 0.45 vs 0.12 to 0.23). The features hold up as analytical units; the branches work as navigation, not as empirical classes.

Python · Embeddings · HDBSCAN · NetworkX · Human review

View repository →

Applied AI and Information Systems

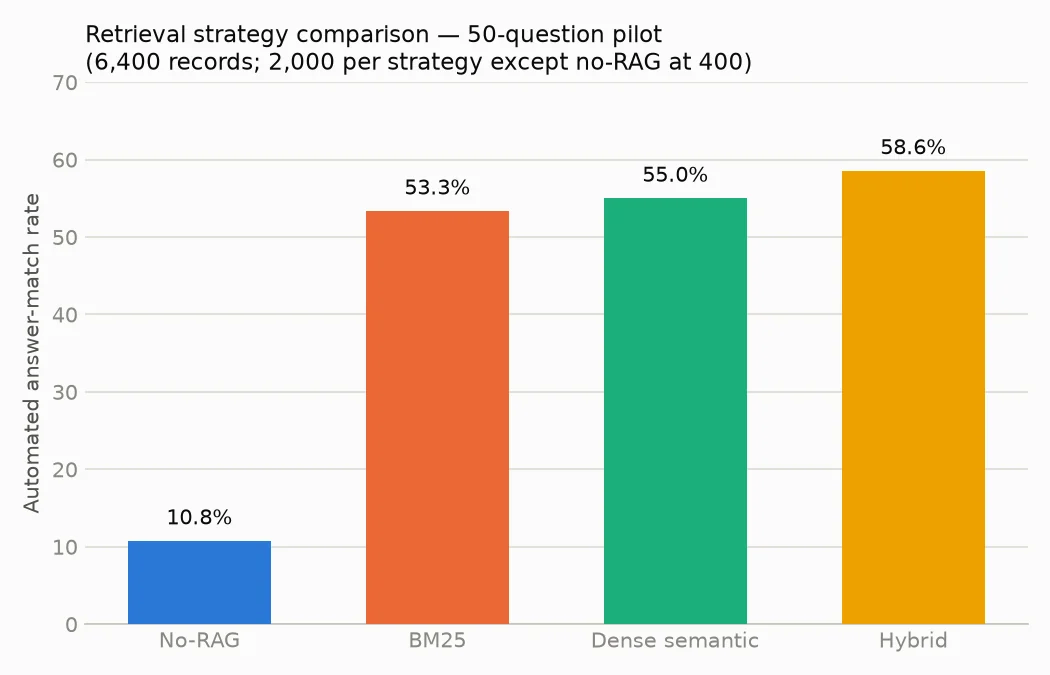
Bar chart of answer-match rate by retrieval strategy: no retrieval 10.8%, BM25 53.3%, dense 55.0%, hybrid 58.6% 2 figures

RAG · Information retrieval · Evaluation

DOME Handbook RAG

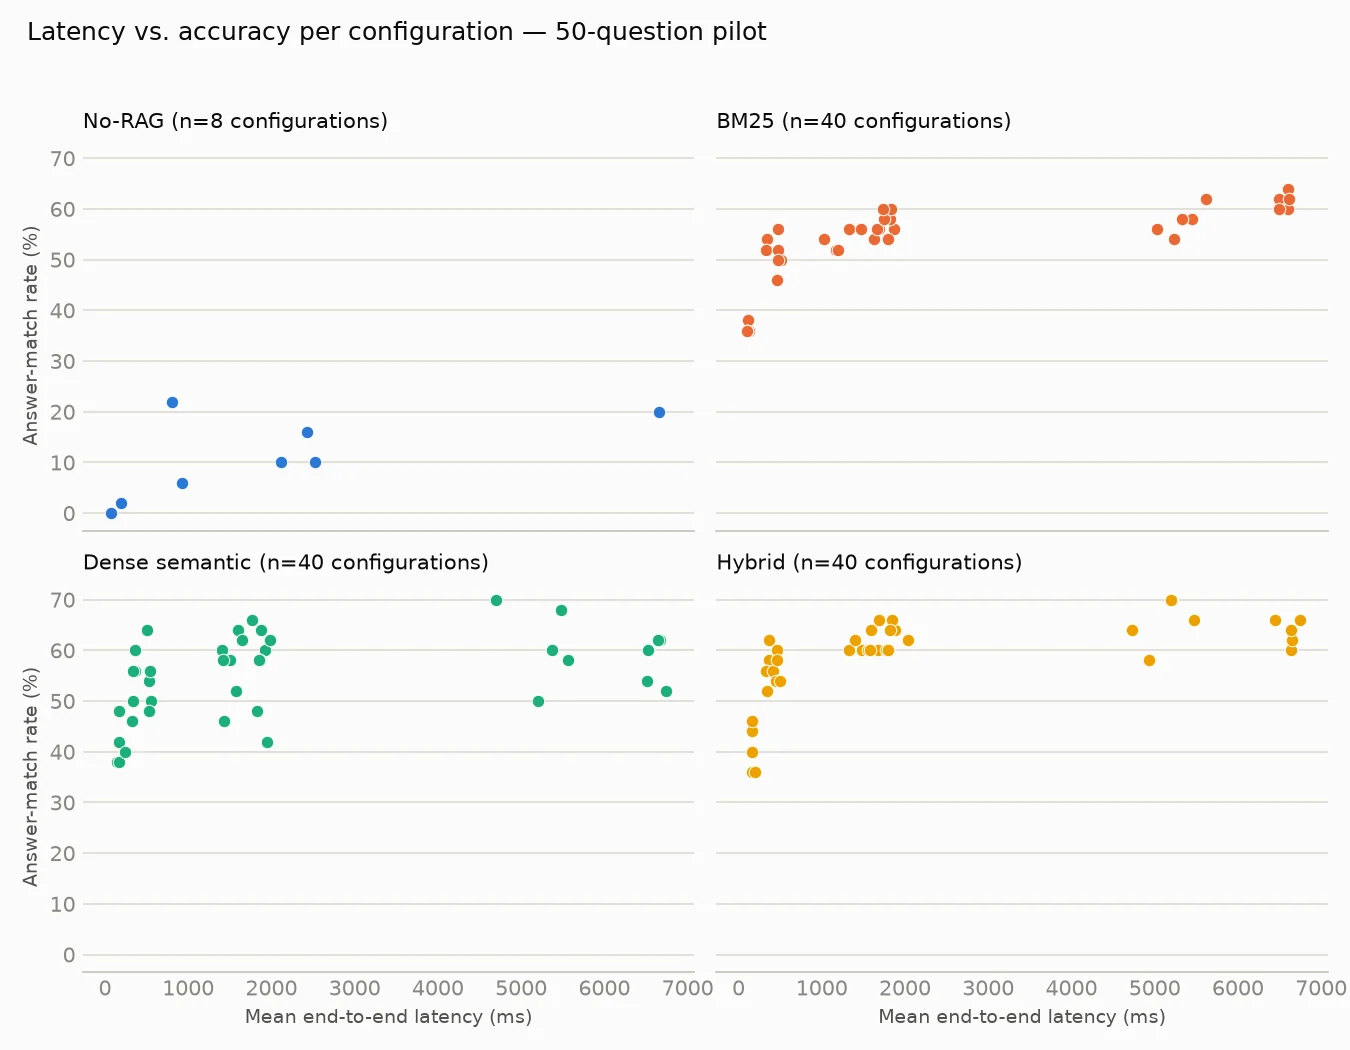
A local RAG system for an engineering handbook, plus two studies comparing retrieval strategies, embeddings, and language models across 6,672 question-level records.

Key findingHybrid retrieval reached a 58.6% answer-match rate against 10.8% with no retrieval, and the best single configurations reached 70%.

LangChain · ChromaDB · BM25 · Ollama · Gradio
View repository →

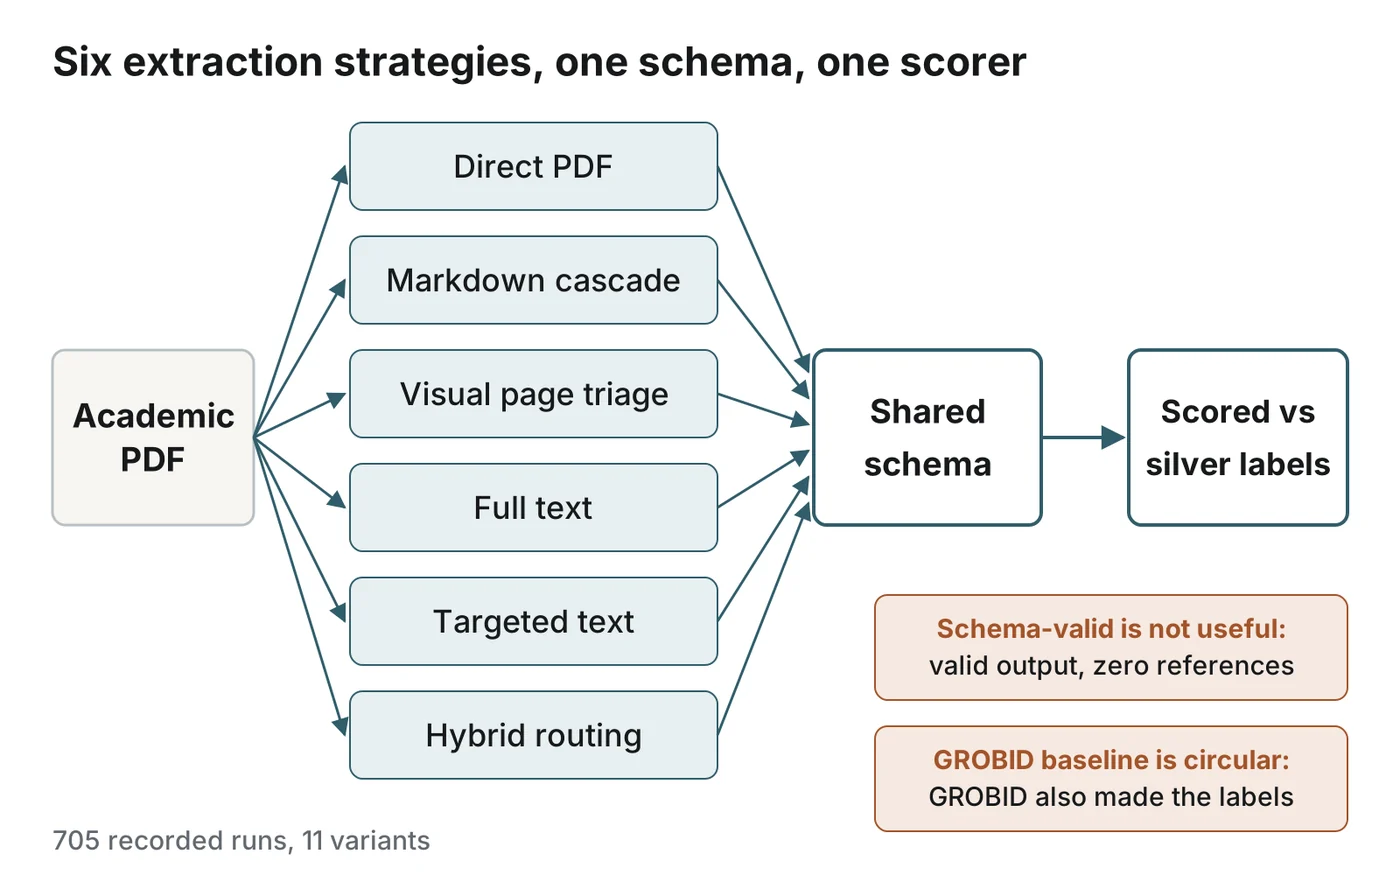
Diagram: an academic PDF flows through six extraction strategies into a shared schema and is scored against silver labels, with two caveats noted

Document intelligence · Benchmarking · Reproducibility

CiteBench

A benchmark comparing six citation-extraction strategies and two parser baselines on academic PDFs, under one output schema and one scorer.

Key findingSchema-valid output was not the same as useful output: the hybrid workflow returned structurally valid responses with no references. The GROBID baseline’s high agreement is circular, because GROBID also produced the labels.

Python · PDF parsing · LLM evaluation · Schema validation
View repository →

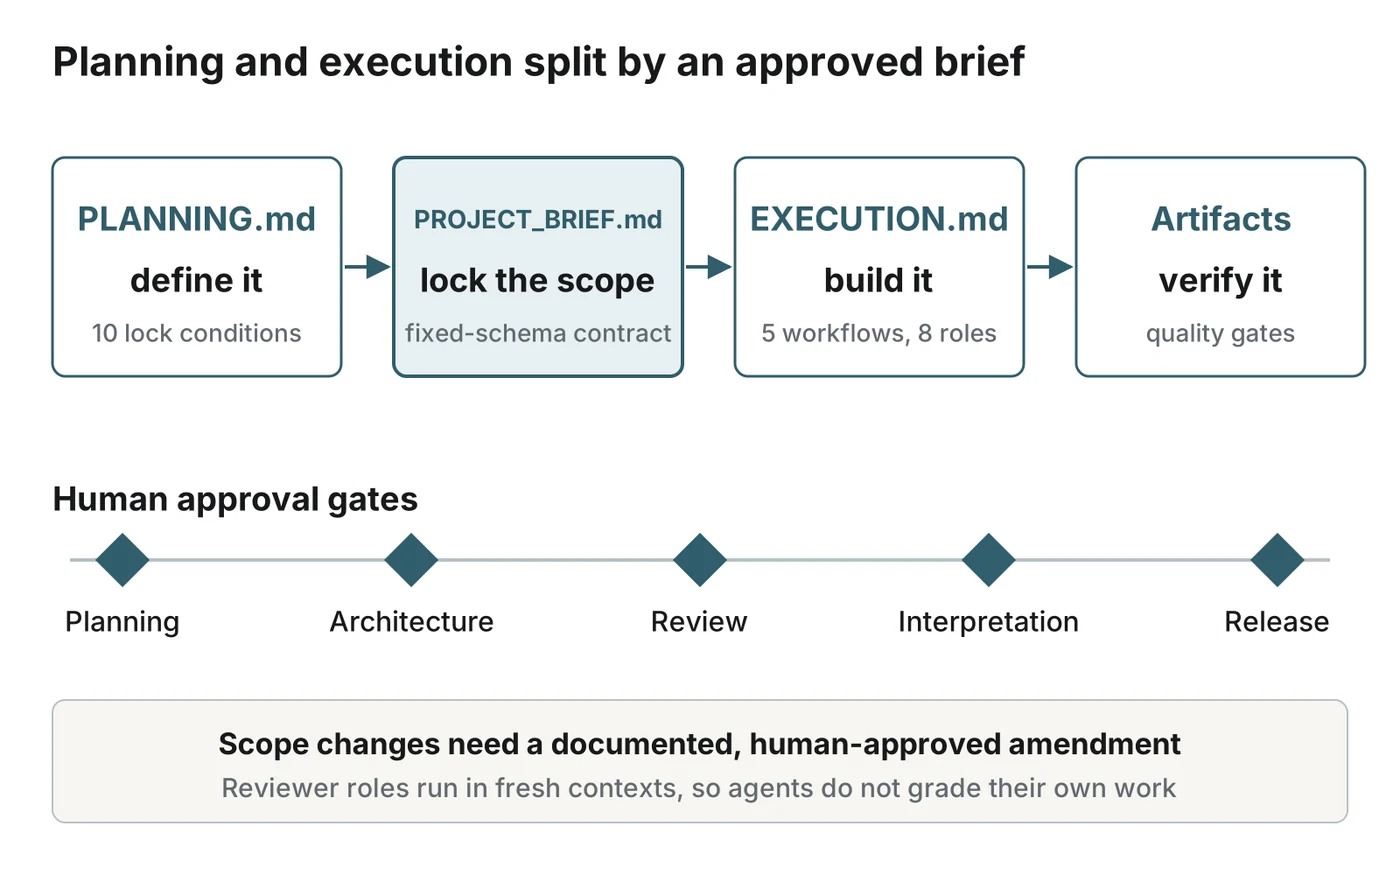
Diagram: PLANNING.md produces an approved PROJECT_BRIEF.md, which EXECUTION.md turns into verified artifacts, with human approval gates at planning, architecture, review, interpretation, and release

Agentic systems · Quality gates · Reproducibility

Agentic Development Workflow

A file-based methodology for running analytics and AI projects with coding agents, where an approved project brief separates planning from execution.

DesignTen lock conditions gate planning; eight agent roles and five workflows run execution; reviewer roles work in fresh contexts so agents do not grade their own output.

AI agents · Human in the loop · Project planning · Documentation
View repository →

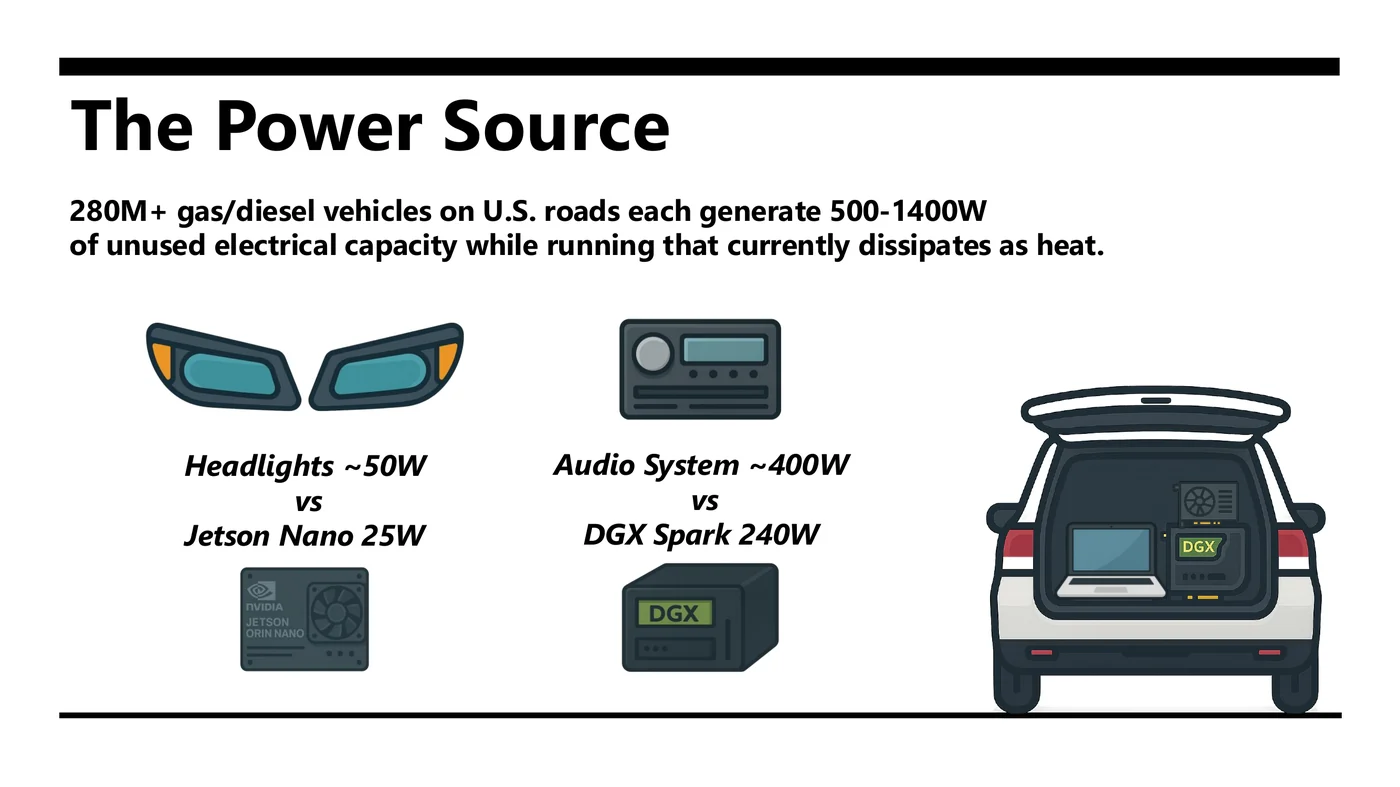
Title slide: Wasted Momentum, A Study of Vehicle-Powered Edge AI, with an SUV connected to an AI compute unit 3 figures

Edge AI · Feasibility study · Research proposal

Wasted Momentum: Vehicle-Powered Edge AI

A feasibility framework and six-month validation plan for running AI inference on vehicle power in places centralized compute cannot reach.

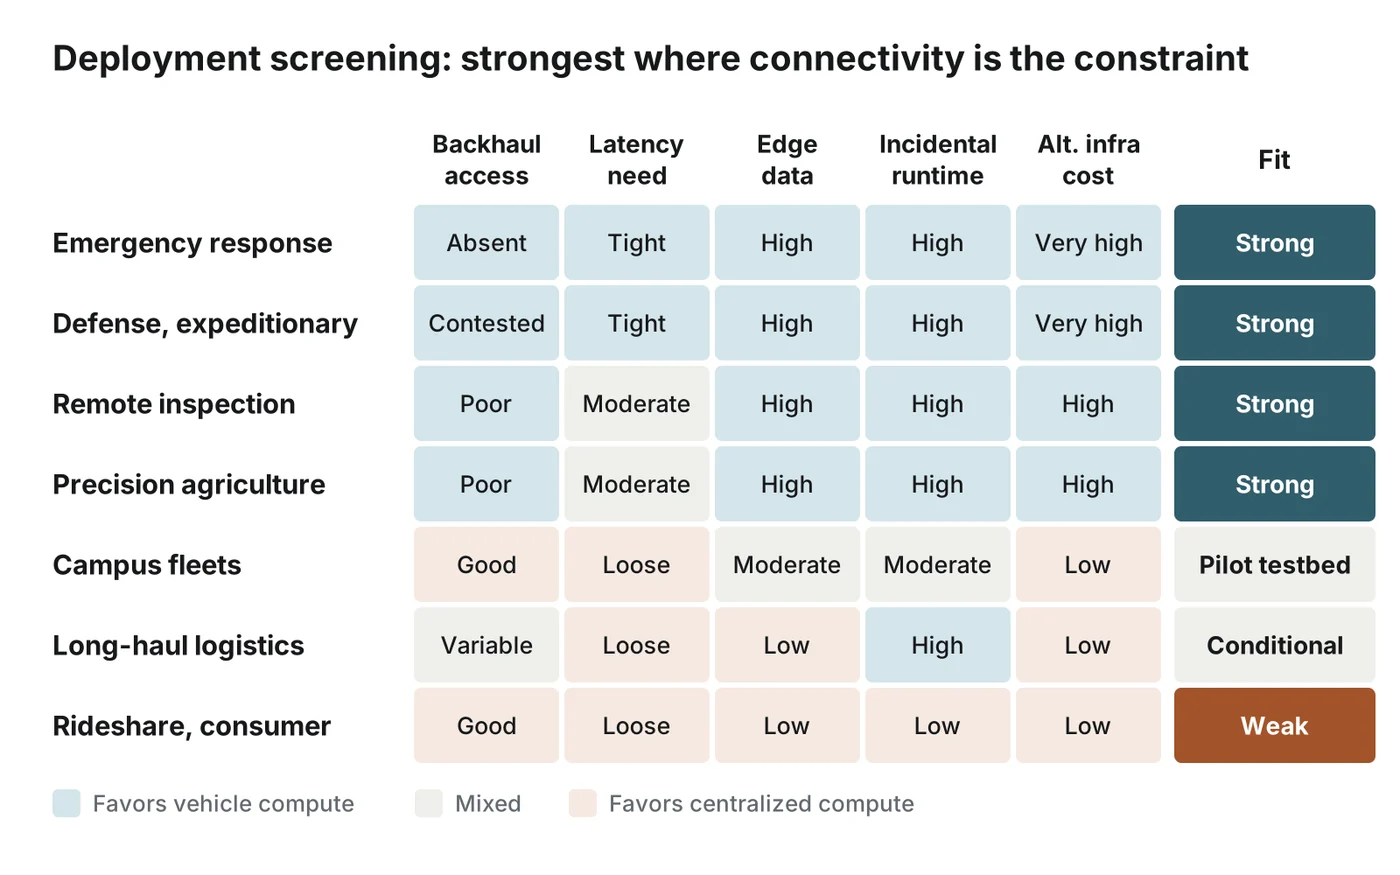
Core argumentVehicle power is not cheaper than grid power, so the case is compute availability. Emergency response, defense, remote inspection, and agriculture screen as strong fits; rideshare and consumer fleets rank last.

First place, 2025 SUNY Polytechnic Institute Elevator Pitch Competition

White paper (PDF) → Pitch deck (PDF) →

Contact

Email is the fastest way to reach me: Jacob.Willson13@gmail.com

Email LinkedIn GitHub

© 2026 Jacob Willson